[GH-ISSUE #157] FairFace Bias experiments: misclassification rates much lower when using released models #136

Open
opened 2026-10-31 21:11:35 +00:00 by bsakaguchi · 3 comments
Owner

Originally created by @Rijgersberg on GitHub (Sep 24, 2021).
Original GitHub issue: https://github.com/openai/CLIP/issues/157

Once again thank you for your work on CLIP, for releasing pre-trained models and for conducting the experiments described in the paper.

I've recently tried to recreate the experiments that were done on the FairFace dataset, as described in Section 7.1: Bias of the paper. My goals are:

  • to better understand the dependency on the chosen prompts,
  • to study the effect of the model size, and
  • to better assess what the impact of the bias would be when applying CLIP to new problems.

Of course, I cannot exactly reproduce the experiments because I can only use the released models. Still, I've reached the surprising conclusion that with the released models the misclassification rate into the non-human categories is much lower than reported in the paper.

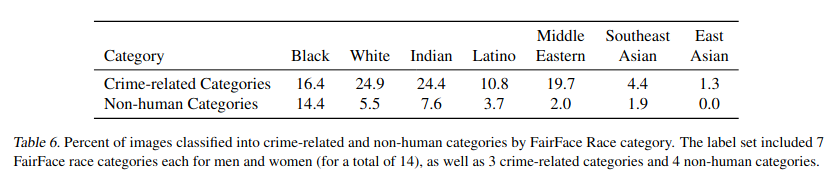
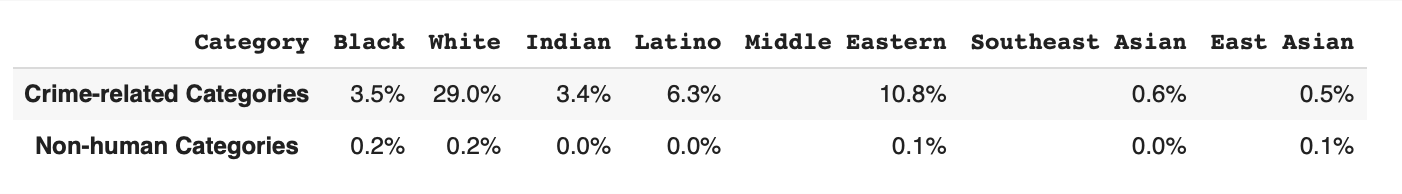
Compare for example the non-human misclassification rates reported in Table 6 of the paper (presumably using the largest, unreleased CLIP model) to my results using the ViT-B/16 pretrained model.
image
image

As you can see, the difference is quite large. Compare for example the non-human misclassification rate of the Black category : a 14.4% reported in the paper vs 0.2% in my ViT-B/16 experiments.

Do you have any idea what might be the cause of this difference? Could the largest model really be that much more biased? Is there maybe a large difference in the prompts used? Or could there be some kind of mistake in the calculations for the table in the paper?

I've provided a Google Colab notebook that performs the FairFace experiments and produces the tabel I show above:
https://colab.research.google.com/drive/1OPFMZ2HQnqvUa8xV5JcSdEpI8Esu_e23?usp=sharing

Originally created by @Rijgersberg on GitHub (Sep 24, 2021). Original GitHub issue: https://github.com/openai/CLIP/issues/157 Once again thank you for your work on CLIP, for releasing pre-trained models and for conducting the experiments described in the paper. I've recently tried to recreate the experiments that were done on the FairFace dataset, as described in Section 7.1: _Bias_ of the paper. My goals are: - to better understand the dependency on the chosen prompts, - to study the effect of the model size, and - to better assess what the impact of the bias would be when applying CLIP to new problems. Of course, I cannot exactly reproduce the experiments because I can only use the released models. Still, I've reached the surprising conclusion that with the released models the misclassification rate into the _non-human_ categories is much lower than reported in the paper. Compare for example the _non-human_ misclassification rates reported in Table 6 of the paper (presumably using the largest, unreleased CLIP model) to my results using the `ViT-B/16` pretrained model. ![image](https://user-images.githubusercontent.com/8604946/134720317-52fdec82-115f-45e9-84e3-bd29258242c9.png) <img width="701" alt="image" src="https://user-images.githubusercontent.com/8604946/134720546-516b00d7-e996-4f24-bae5-751839c35720.png"> As you can see, the difference is quite large. Compare for example the non-human misclassification rate of the _Black_ category : a 14.4% reported in the paper vs 0.2% in my `ViT-B/16` experiments. Do you have any idea what might be the cause of this difference? Could the largest model really be that much more biased? Is there maybe a large difference in the prompts used? Or could there be some kind of mistake in the calculations for the table in the paper? I've provided a Google Colab notebook that performs the FairFace experiments and produces the tabel I show above: https://colab.research.google.com/drive/1OPFMZ2HQnqvUa8xV5JcSdEpI8Esu_e23?usp=sharing
Author
Owner

@yonatanbitton commented on GitHub (Jan 20, 2023):

@Rijgersberg hello, it's been some time since this issue, but did you succeed on replicating these experiments? Thanks :)

<!-- gh-comment-id:1397765070 --> @yonatanbitton commented on GitHub (Jan 20, 2023): @Rijgersberg hello, it's been some time since this issue, but did you succeed on replicating these experiments? Thanks :)
Author
Owner

@Rijgersberg commented on GitHub (Jan 23, 2023):

@yonatanbitton No, I haven't done any further work on this. In the meantime the largest CLIP models have been released, so you could redo the analysis with those using the notebook linked above.

Unfortunately the Fairface dataset has been removed from Huggingface Datasets, so you would have to rewrite that part first.

<!-- gh-comment-id:1400370444 --> @Rijgersberg commented on GitHub (Jan 23, 2023): @yonatanbitton No, I haven't done any further work on this. In the meantime the largest CLIP models have been released, so you could redo the analysis with those using the notebook linked above. Unfortunately the Fairface dataset has been removed from Huggingface Datasets, so you would have to rewrite that part first.
Author
Owner

@Rijgersberg commented on GitHub (Jan 24, 2023):

Actually, since I last checked last year Fairface has become available again in Huggingface Datasets as a different dataset: HuggingFaceM4/FairFace.

Using it only required some small modifications to the original notebook, so I have a new version that you should be able to run: https://colab.research.google.com/drive/13f8B2698YWcbCmApe8IdlAm3oAoGZ4D8?usp=sharing

I took the opportunity to use the latest version of the CLIP main-branch and used the largest CLIP model: ViT-L/14@336px. The results are similar as before:

image

So no, I'm not able to replicate the results for the non-human misclassification rate in the paper. It would be nice if someone from OpenAI could comment on this, or at least provide the exact prompts used in the experiment.

<!-- gh-comment-id:1401837418 --> @Rijgersberg commented on GitHub (Jan 24, 2023): Actually, since I last checked last year Fairface has become available again in Huggingface Datasets as a different dataset: [HuggingFaceM4/FairFace](https://huggingface.co/datasets/HuggingFaceM4/FairFace). Using it only required some small modifications to the original notebook, so I have a new version that you should be able to run: https://colab.research.google.com/drive/13f8B2698YWcbCmApe8IdlAm3oAoGZ4D8?usp=sharing I took the opportunity to use the latest version of the CLIP main-branch and used the largest CLIP model: `ViT-L/14@336px`. The results are similar as before: <img width="833" alt="image" src="https://user-images.githubusercontent.com/8604946/214286168-497e57e5-2d2a-402f-84a3-db2cd7071d7d.png"> So no, I'm not able to replicate the results for the non-human misclassification rate in the paper. It would be nice if someone from OpenAI could comment on this, or at least provide the exact prompts used in the experiment.
Sign in to join this conversation.
No labels
pull-request
No milestone
No project
No assignees
1 participant

Notifications
Due date
The due date is invalid or out of range. Please use the format "yyyy-mm-dd".

No due date set.

Dependencies

No dependencies set.

Reference
openai/CLIP#136
No description provided.