- Python 98%
- HTML 1.3%
- Shell 0.7%
|
|
||
|---|---|---|
| .github | ||
| assets | ||
| boosty_downloader | ||
| docs | ||
| scripts | ||
| test | ||
| tools | ||
| .editorconfig | ||
| .env.example | ||
| .gitignore | ||
| .python-version | ||
| CHANGELOG.md | ||
| CONTRIBUTING.md | ||
| LICENSE | ||
| pyproject.toml | ||
| pyrightconfig.json | ||
| README.md | ||
| ruff.toml | ||
| Taskfile.yml | ||
| uv.lock | ||
🖥️ About
Welcome to the Boosty Downloader project!
This CLI tool allows you to download most of the content from Boosty.to in bulk. The post content itself is saved in html with a little bit of styling.
You can download:
- Boosty Videos
- External Videos (YouTube, Vimeo)
- Files
- Full Post content (including photos and links)
📑 Table of Contents
- 🖥️ About
✨ Features
- 📦 Bulk download: Download all available content from your favorite creator.
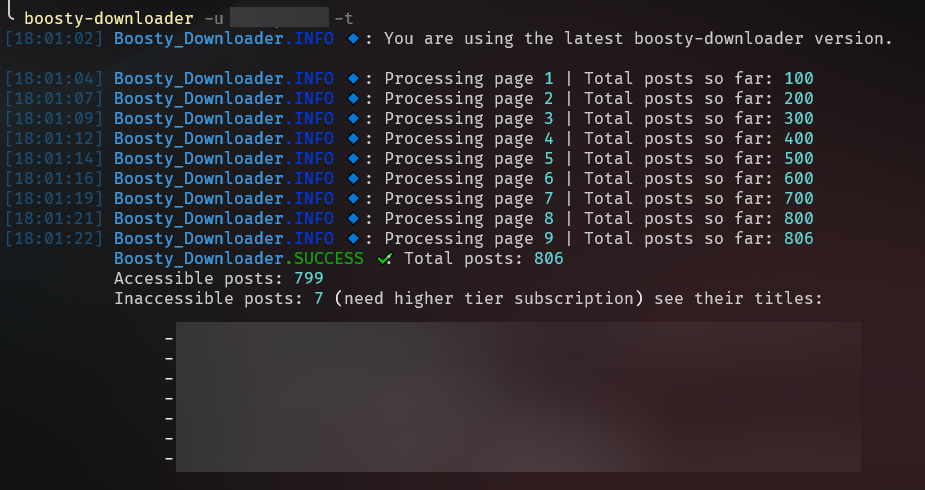
- 🔎 Blog overview:
checkshows what each subscription tier gives (posts and share of the blog), where you stand, what the rest costs, media counts and the posting date range. - 🧪 Dry run:
download --dry-runpreviews a run before you start it: new and updated posts, media to fetch by type and the known download size. - 📈 Run statistics: every download ends with what it did: posts, media by type, total size and time.
- 📂 Content type filters: Download only the content you need (videos, images, etc) with
--content-type-filter. - 📄 Download specific posts: Download post by url and username.
- 🔃 Sync content seamlessly: The utility keeps cache of already downloaded posts, so you can resume your download at any time or get new content after a while.
- 📼 Choose your video quality: You can choose preferred video quality to download (for boosty videos)
- 🎨 Beauty posts preview: You can see posts content with rendered offline html files with dark/light theme changing.
- 📊 Order matters: Posts have dates in names, so you can just sort it by name in your file explorer and see them in the correct chronological order.
- 🆙 App update checker: If new updates are available, you'll be notified when you use the application next time.
- 🔑 Auth helper script: Run
boosty-downloader show-auth-scriptto get a browser console script that extracts your credentials automatically.
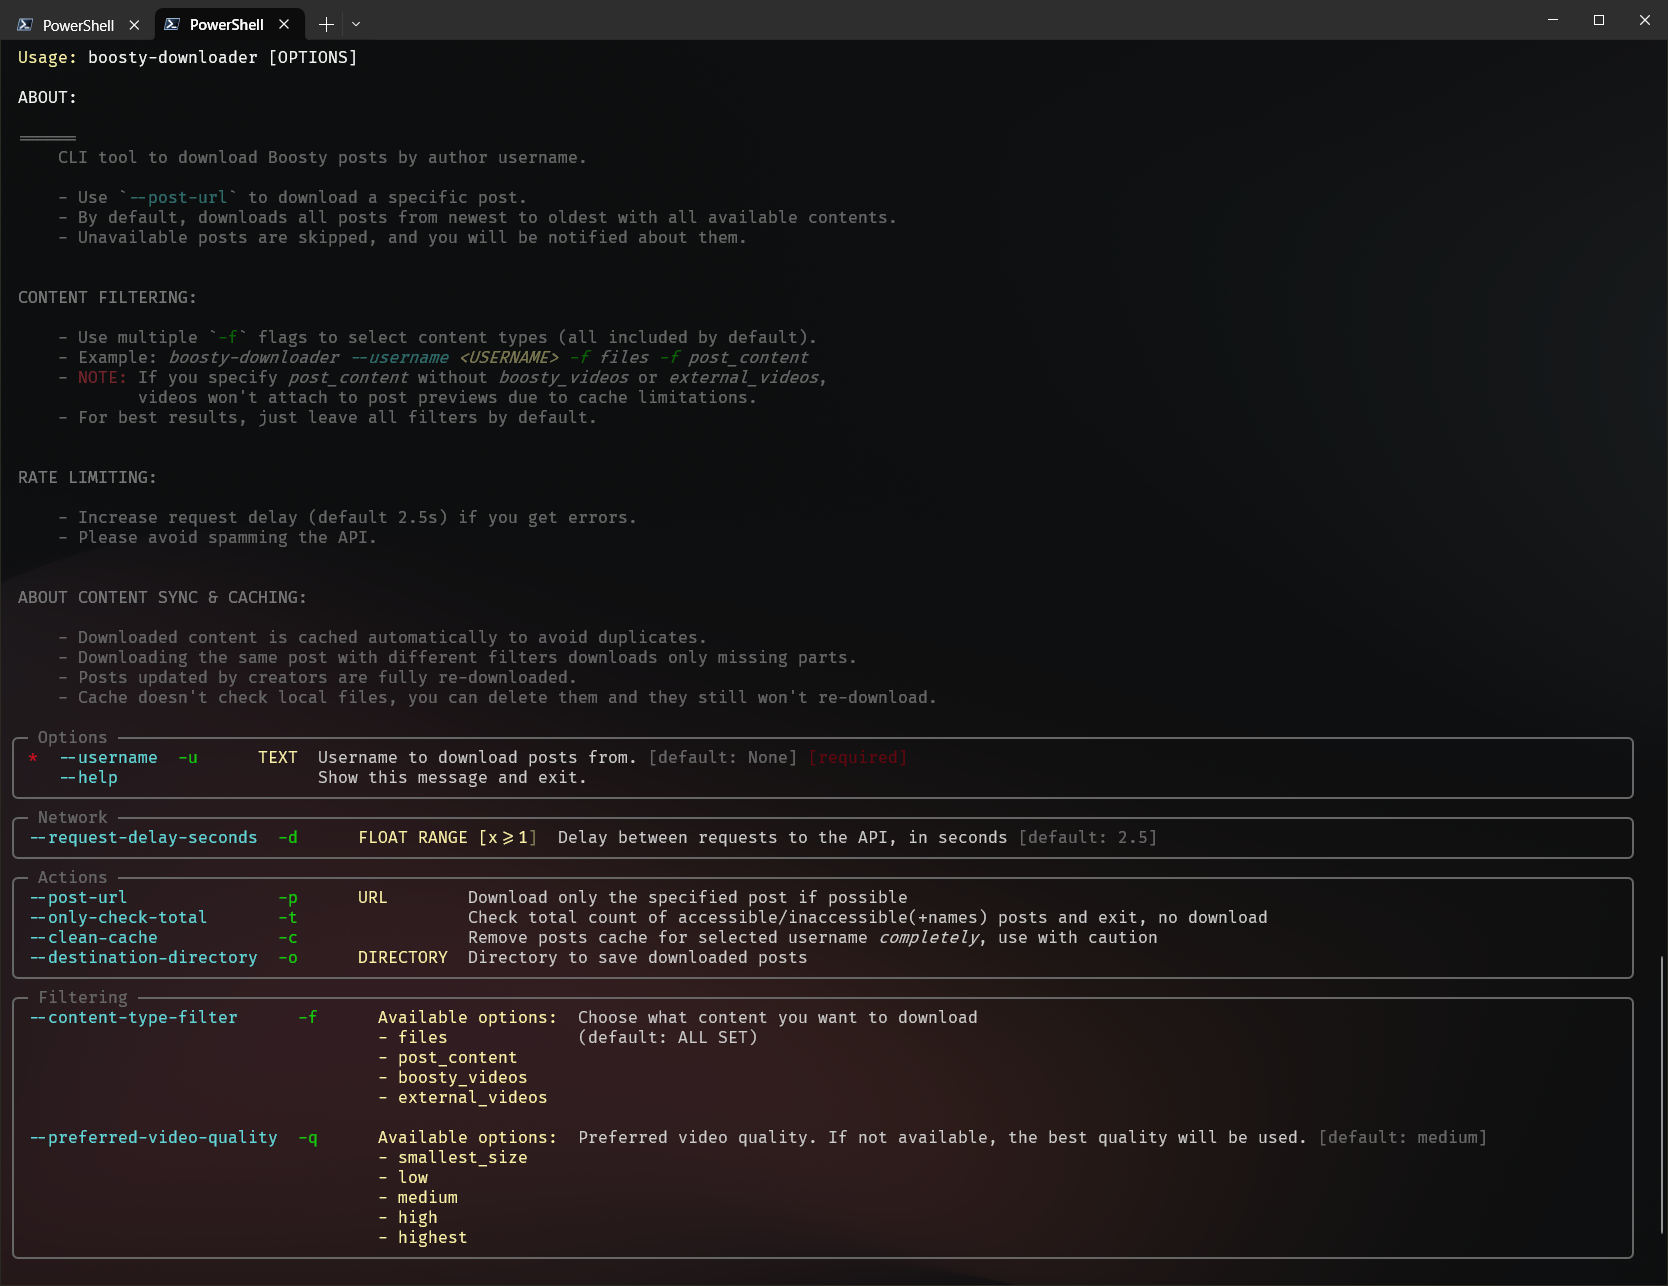
📸 Screenshots & Usage
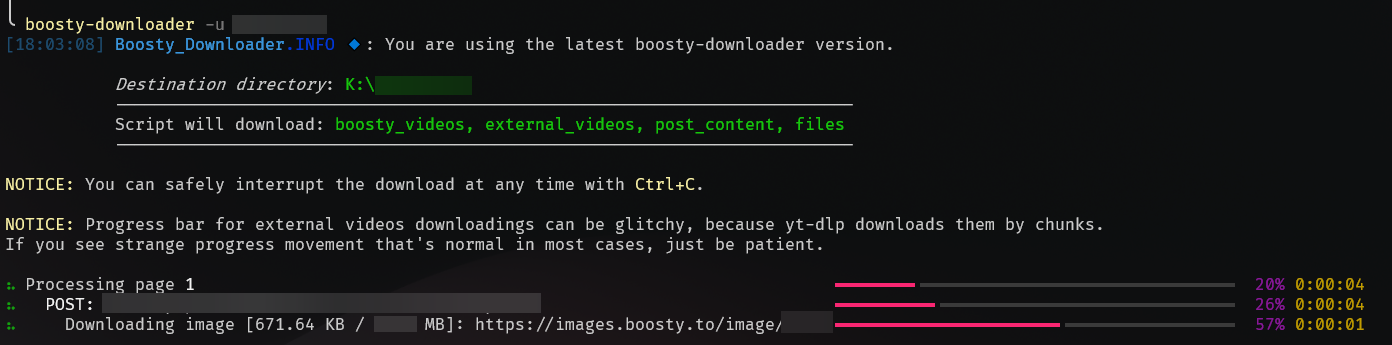
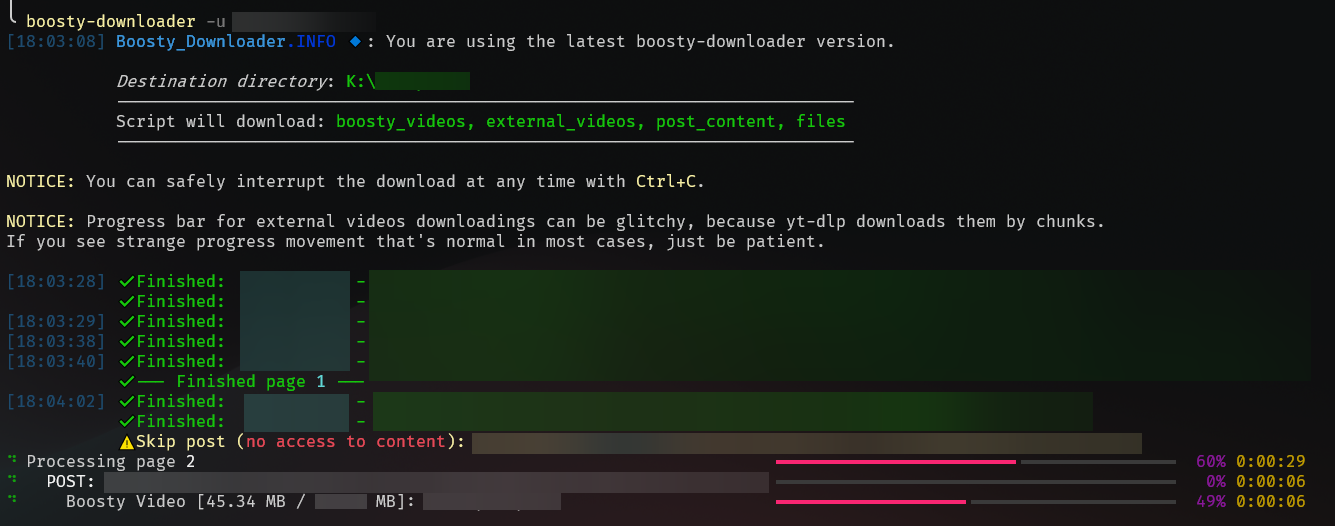
🛠️ Installation
-
Install python:
- Window:
winget install Python.Python.3.13 - Linux:
sudo apt-get install python3 - macOS:
brew install python
- Window:
-
Install the boosty-downloader package:
pip install boosty-downloader -
Run the application:
boosty-downloader --help
🚀 Configuration for Usage
Step 1: Get the auth cookie and auth header
Option 1 - Manually
- Open the Boosty website.
- Click the "Sign in" button and fill you credentials.
- Navigate to any author you have access to and scroll post a little.
- Copy auth token and cookie from browser network tab.
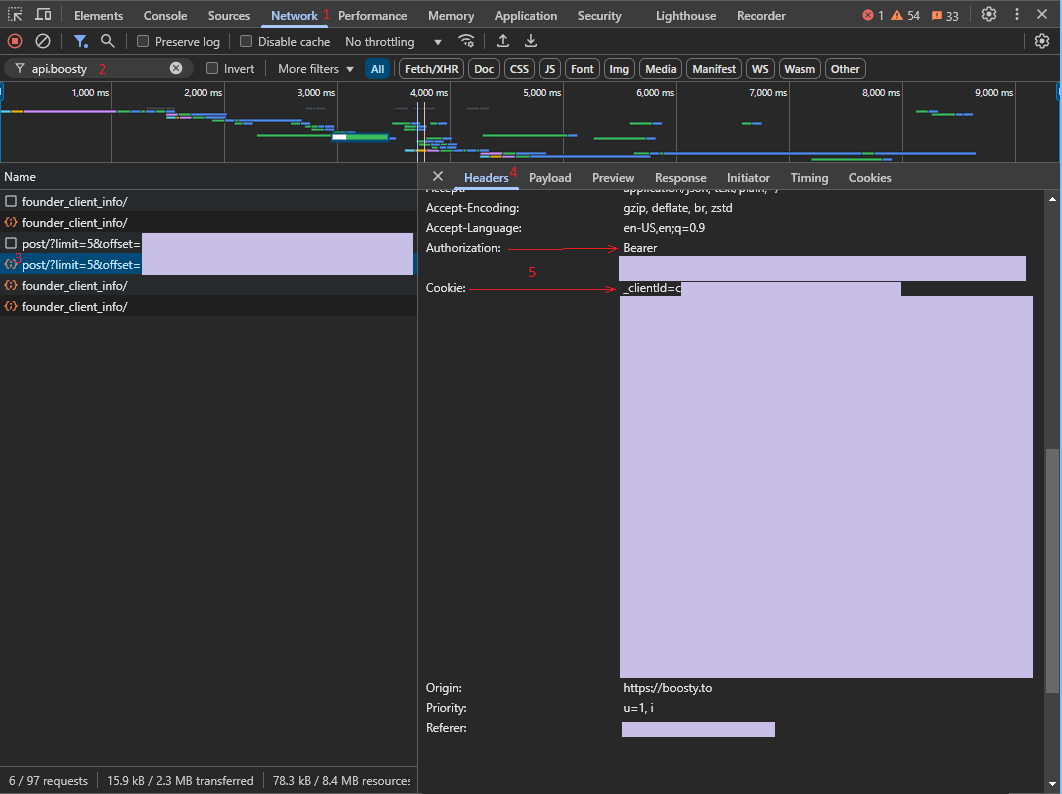
Option 2 - With helper script
- Run
boosty-downloader show-auth-scriptto show the helper script (it will be copied to your clipboard automatically). - Open the Boosty website and log in.
- Open browser console (F12) and paste the script.
- Scroll the page a little - a floating box with your credentials will appear.
Step 2: Paste the cookie and auth header into the config file
This config will be created during first run of the app in the current working directory.
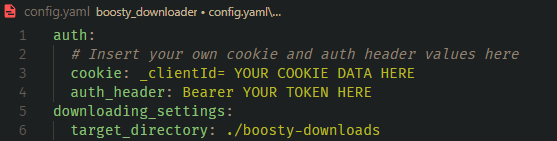
Step 3: Run the utility
Now you can just download your content with the following command:
boosty-downloader download YOUR_CREATOR_NAME
🛡️ When downloads fail
One bad link never costs you the whole run:
- A failed download is retried up to 5 times with growing pauses; a link that expired mid-way is refreshed from the API once.
- A post with one dead link keeps everything else: the parts that finished are remembered right away, and only the failed part is fetched again.
post.htmlis written anyway: a picture, video or audio track that did not download leaves a note at its place with the reason, so the post stays readable. The note goes away once a retry or a later run brings the piece.- A post that still fails is skipped, and the run continues.
- A YouTube or Vimeo video that is gone (deleted, private, blocked) is not retried at all: the post is skipped right away with the site's reason, the rest of it is saved, and the run goes on.
- Every skipped post is written to
failed_downloads.lognext to your downloads. - At the end, a summary lists everything that was skipped and why.
- If 5 posts in a row fail, the downloader stops early: a streak like this means the problem is not in the posts - check your disk, folder permissions, or network.
- Prefer to finish the pass no matter what? Add
--skip-all-failures- the run never stops on a failure streak. download --post-urlgets the same retries and the same refresh as the full run.
Downloaded posts are cached. After you fix the cause, run the same command again - finished posts are skipped in seconds, and the download continues where it stopped.
Can't tell what's breaking? Re-run with --debug: it writes boosty-downloader-debug.log with every request and full error details, safe to attach to a GitHub issue - download links are logged without their signed keys.
💖 Contributing
If you want to contribute to this project, please see the CONTRIBUTING.md.
📜 License
This project is licensed under the MIT License - see the LICENSE file for details.